Sophisticated technology, a legacy product, a team of two
Feedzai builds AI-powered fraud and risk detection for banks. The technology was sophisticated; the legacy Alert Manager analysts acted on it with was not. I joined as the second designer to build the practice, for analysts making hundreds of judgment calls a day.
Design the product. Establish the practice.
- Design Case Manager from scratch: risk and case management, data visualisation, configuration
- Grow the design team from two people to eight
- Build a UX research practice: workshops, personas, usability testing
- Make ML output legible without a data science background
Three people, one queue
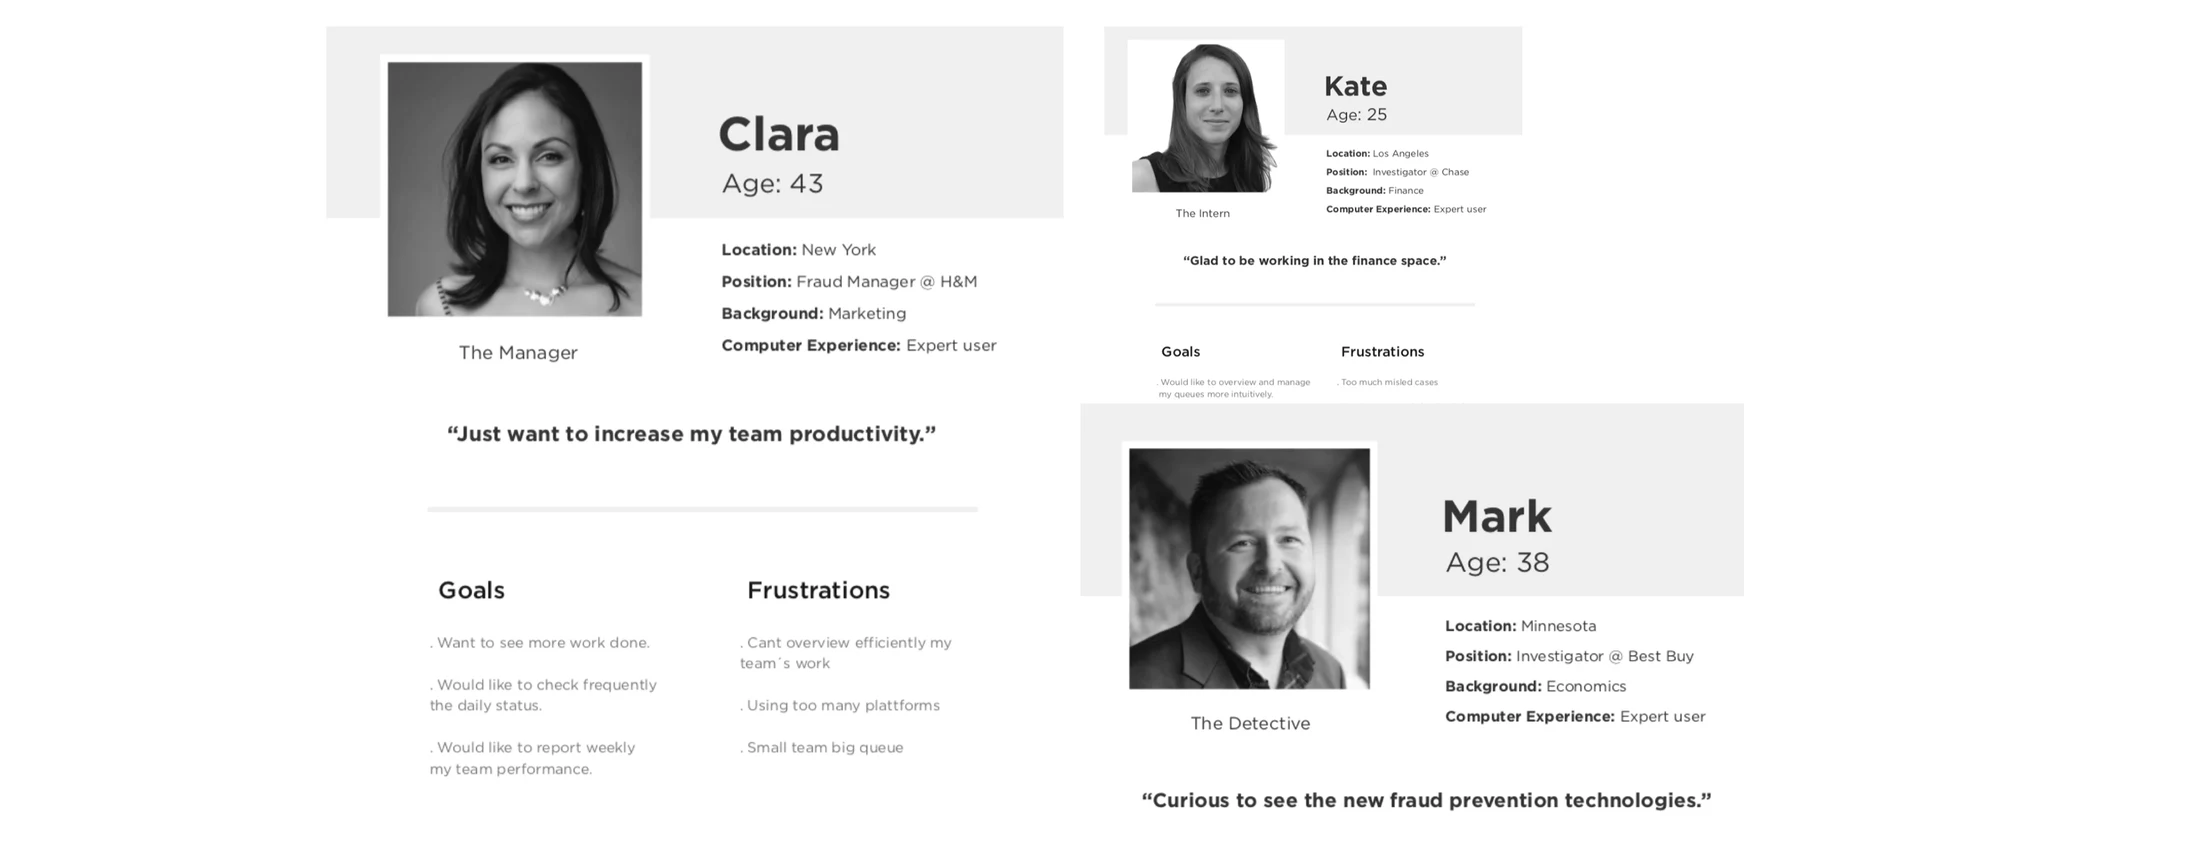
Forty-plus interviews produced three archetypes: a manager answering for throughput, an investigator in the queue all day, a new analyst still learning the work.
Structure before screens
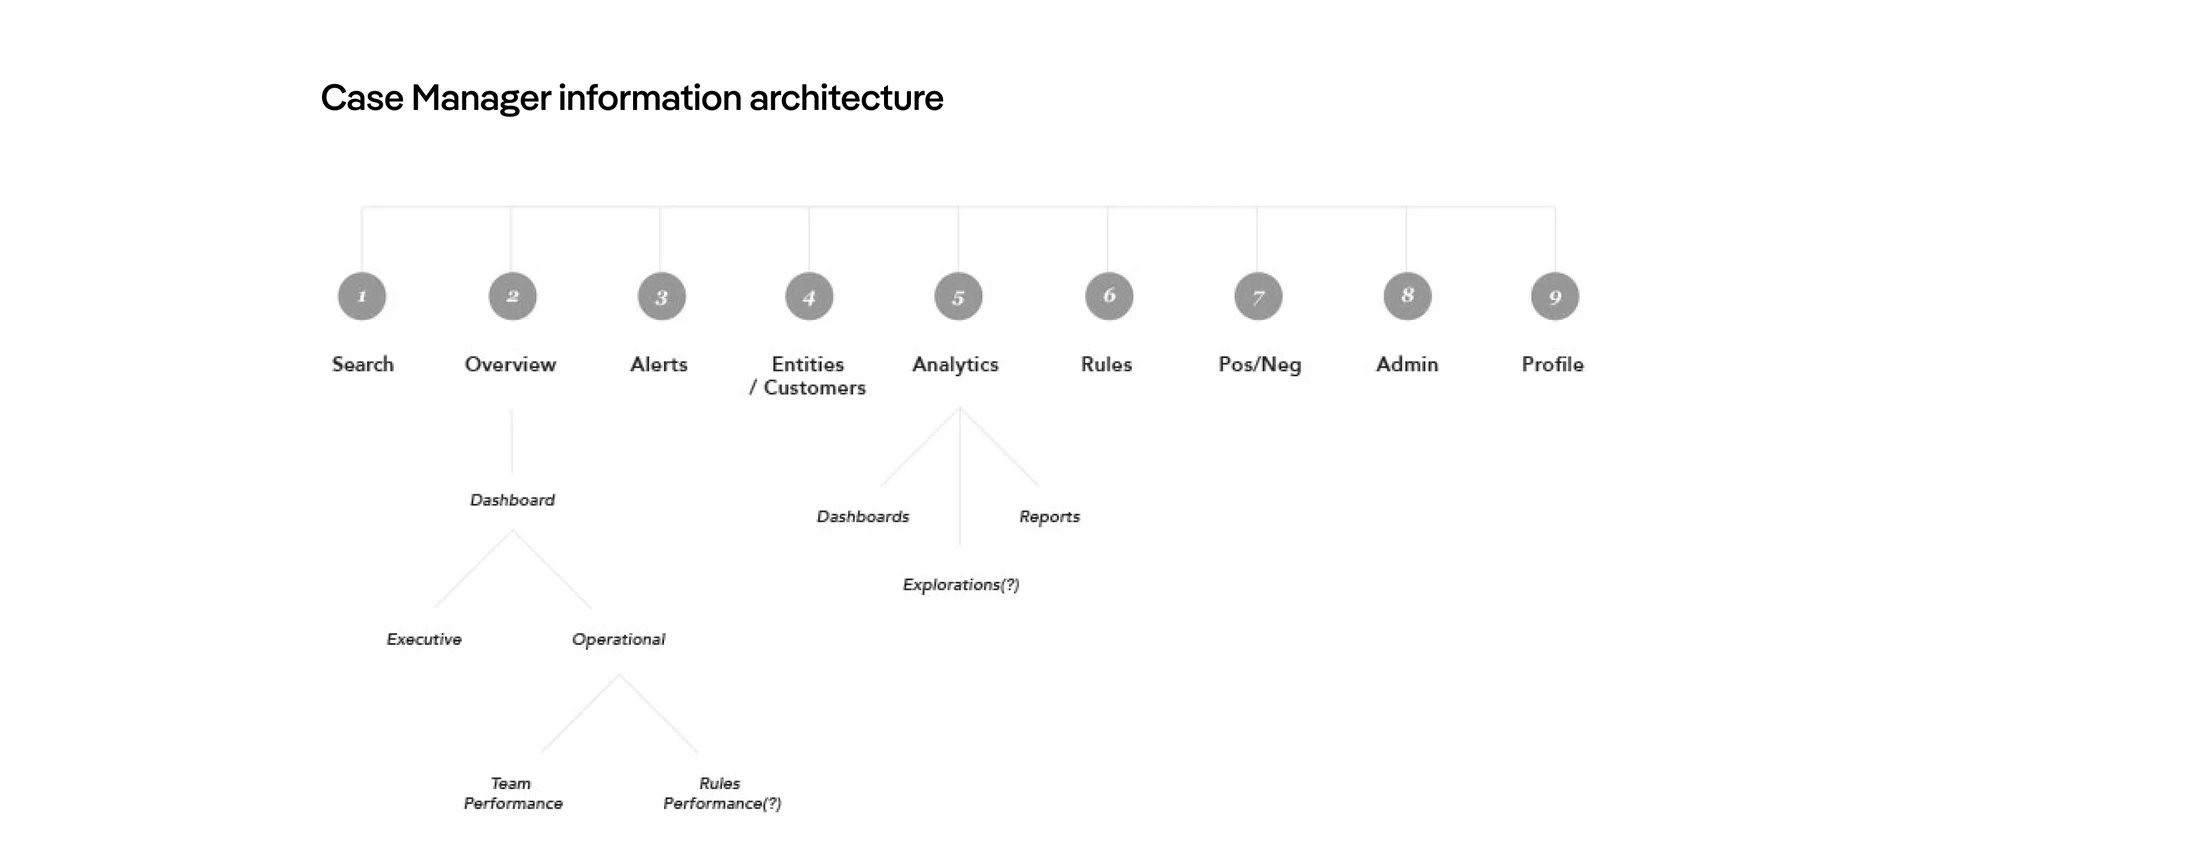
Case Manager needed a structure analysts could hold in their head: nine sections, tested on paper first.
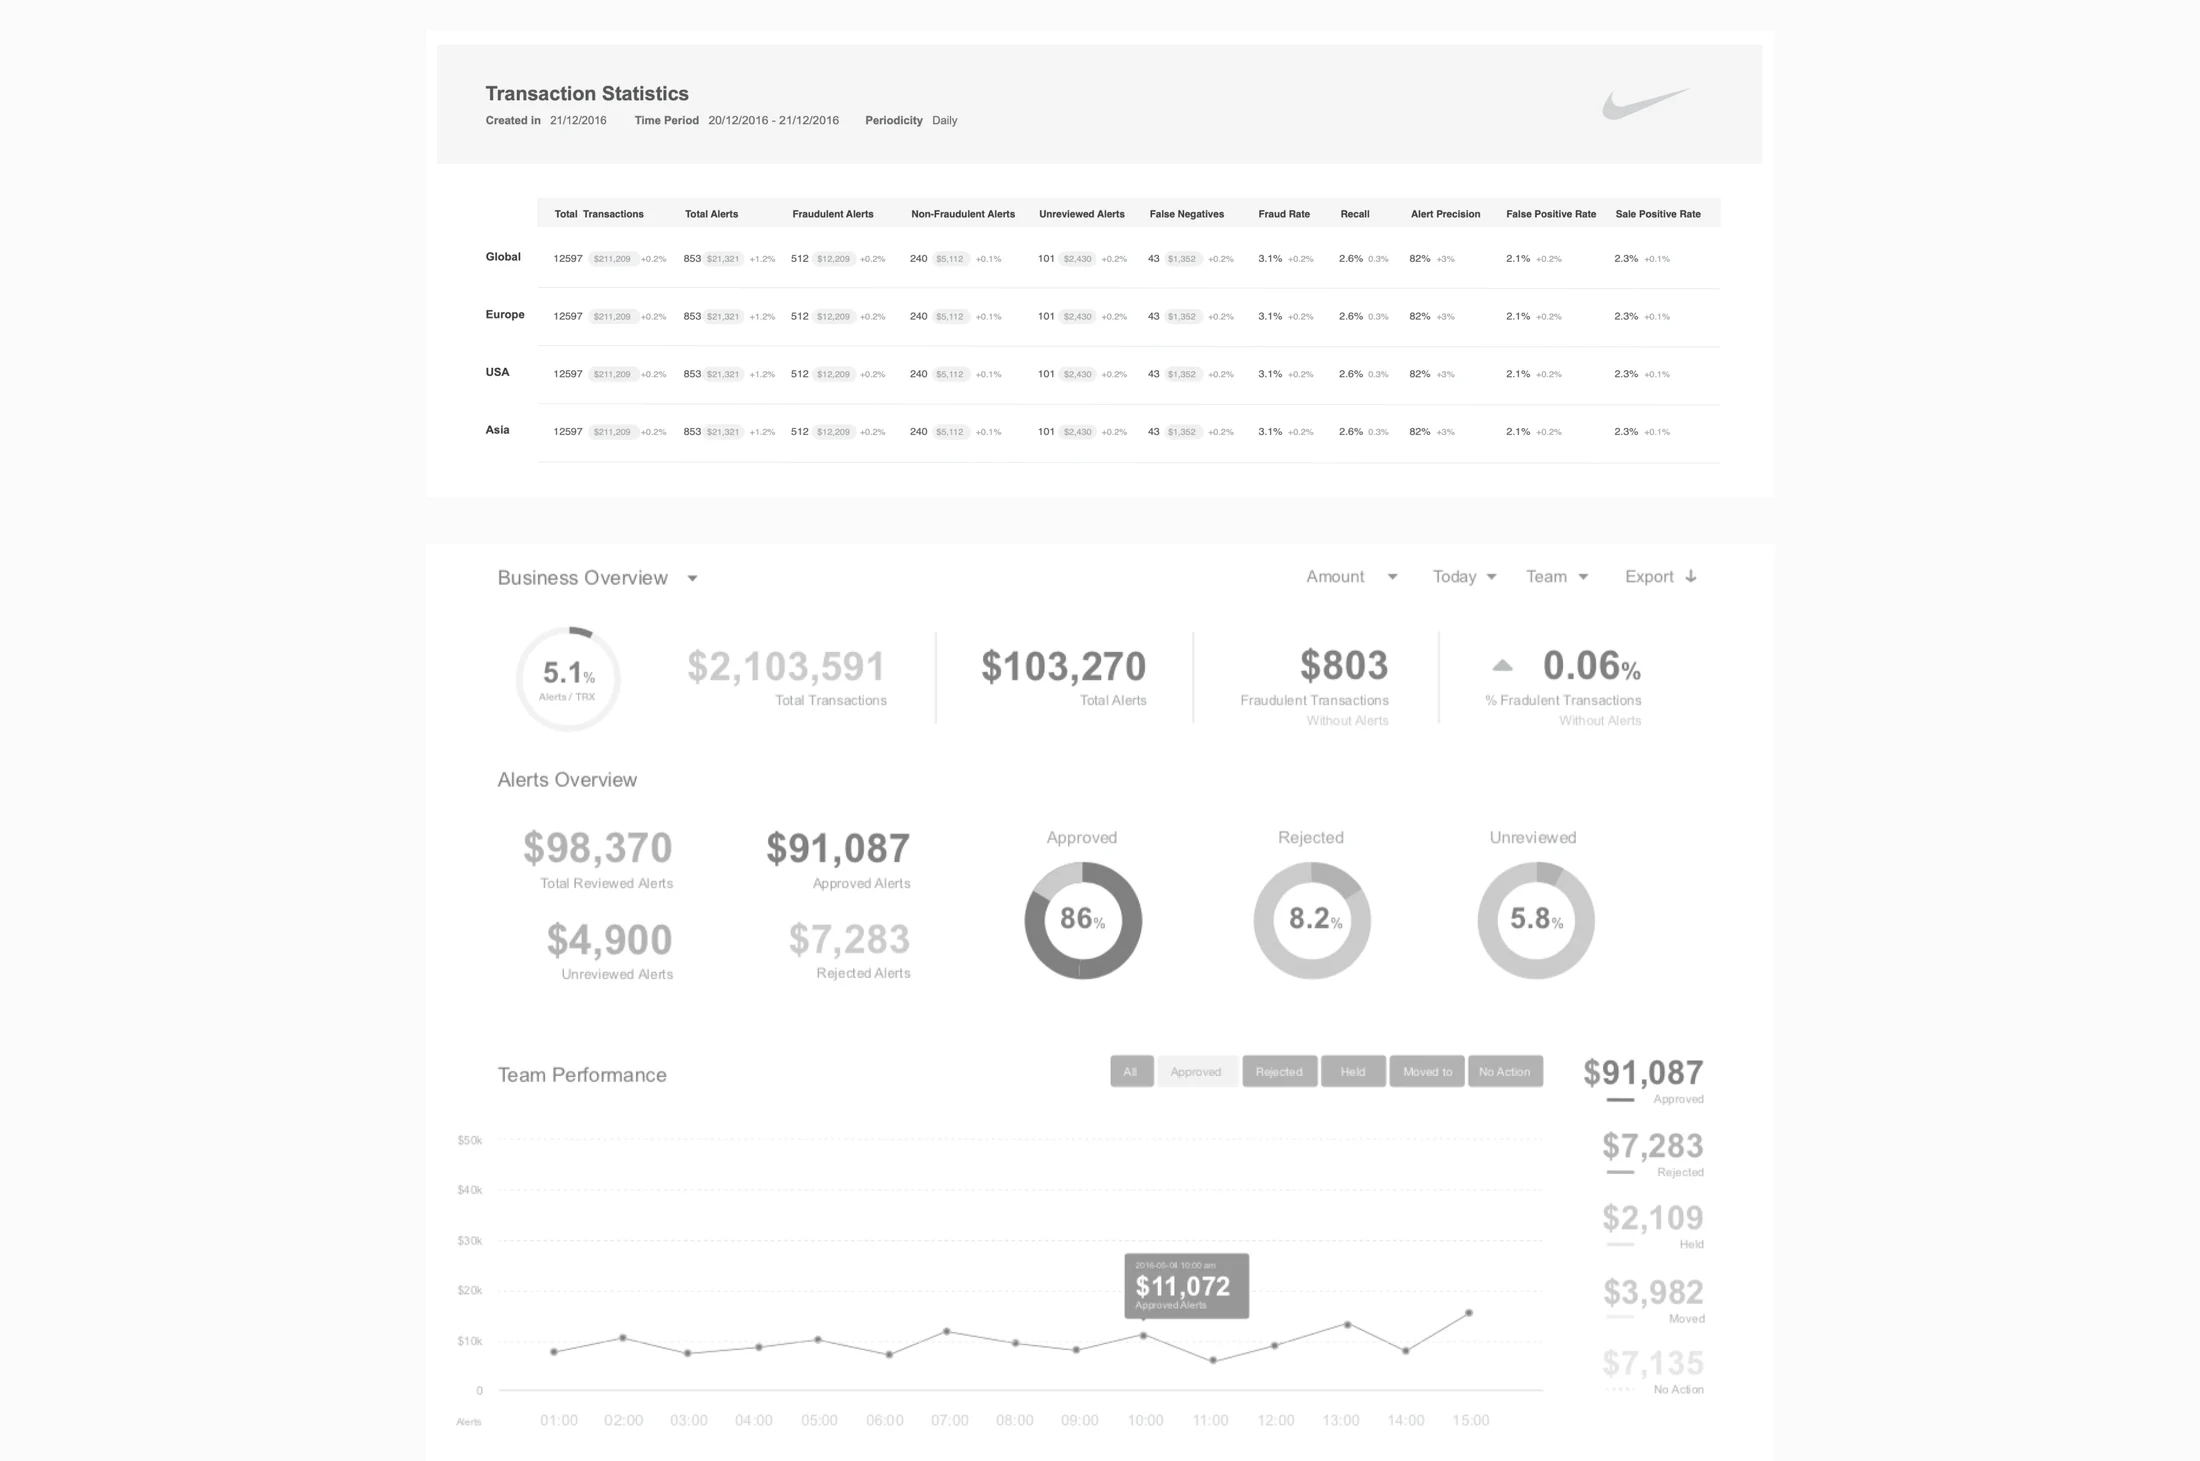
From legacy alert queue to decision workspace
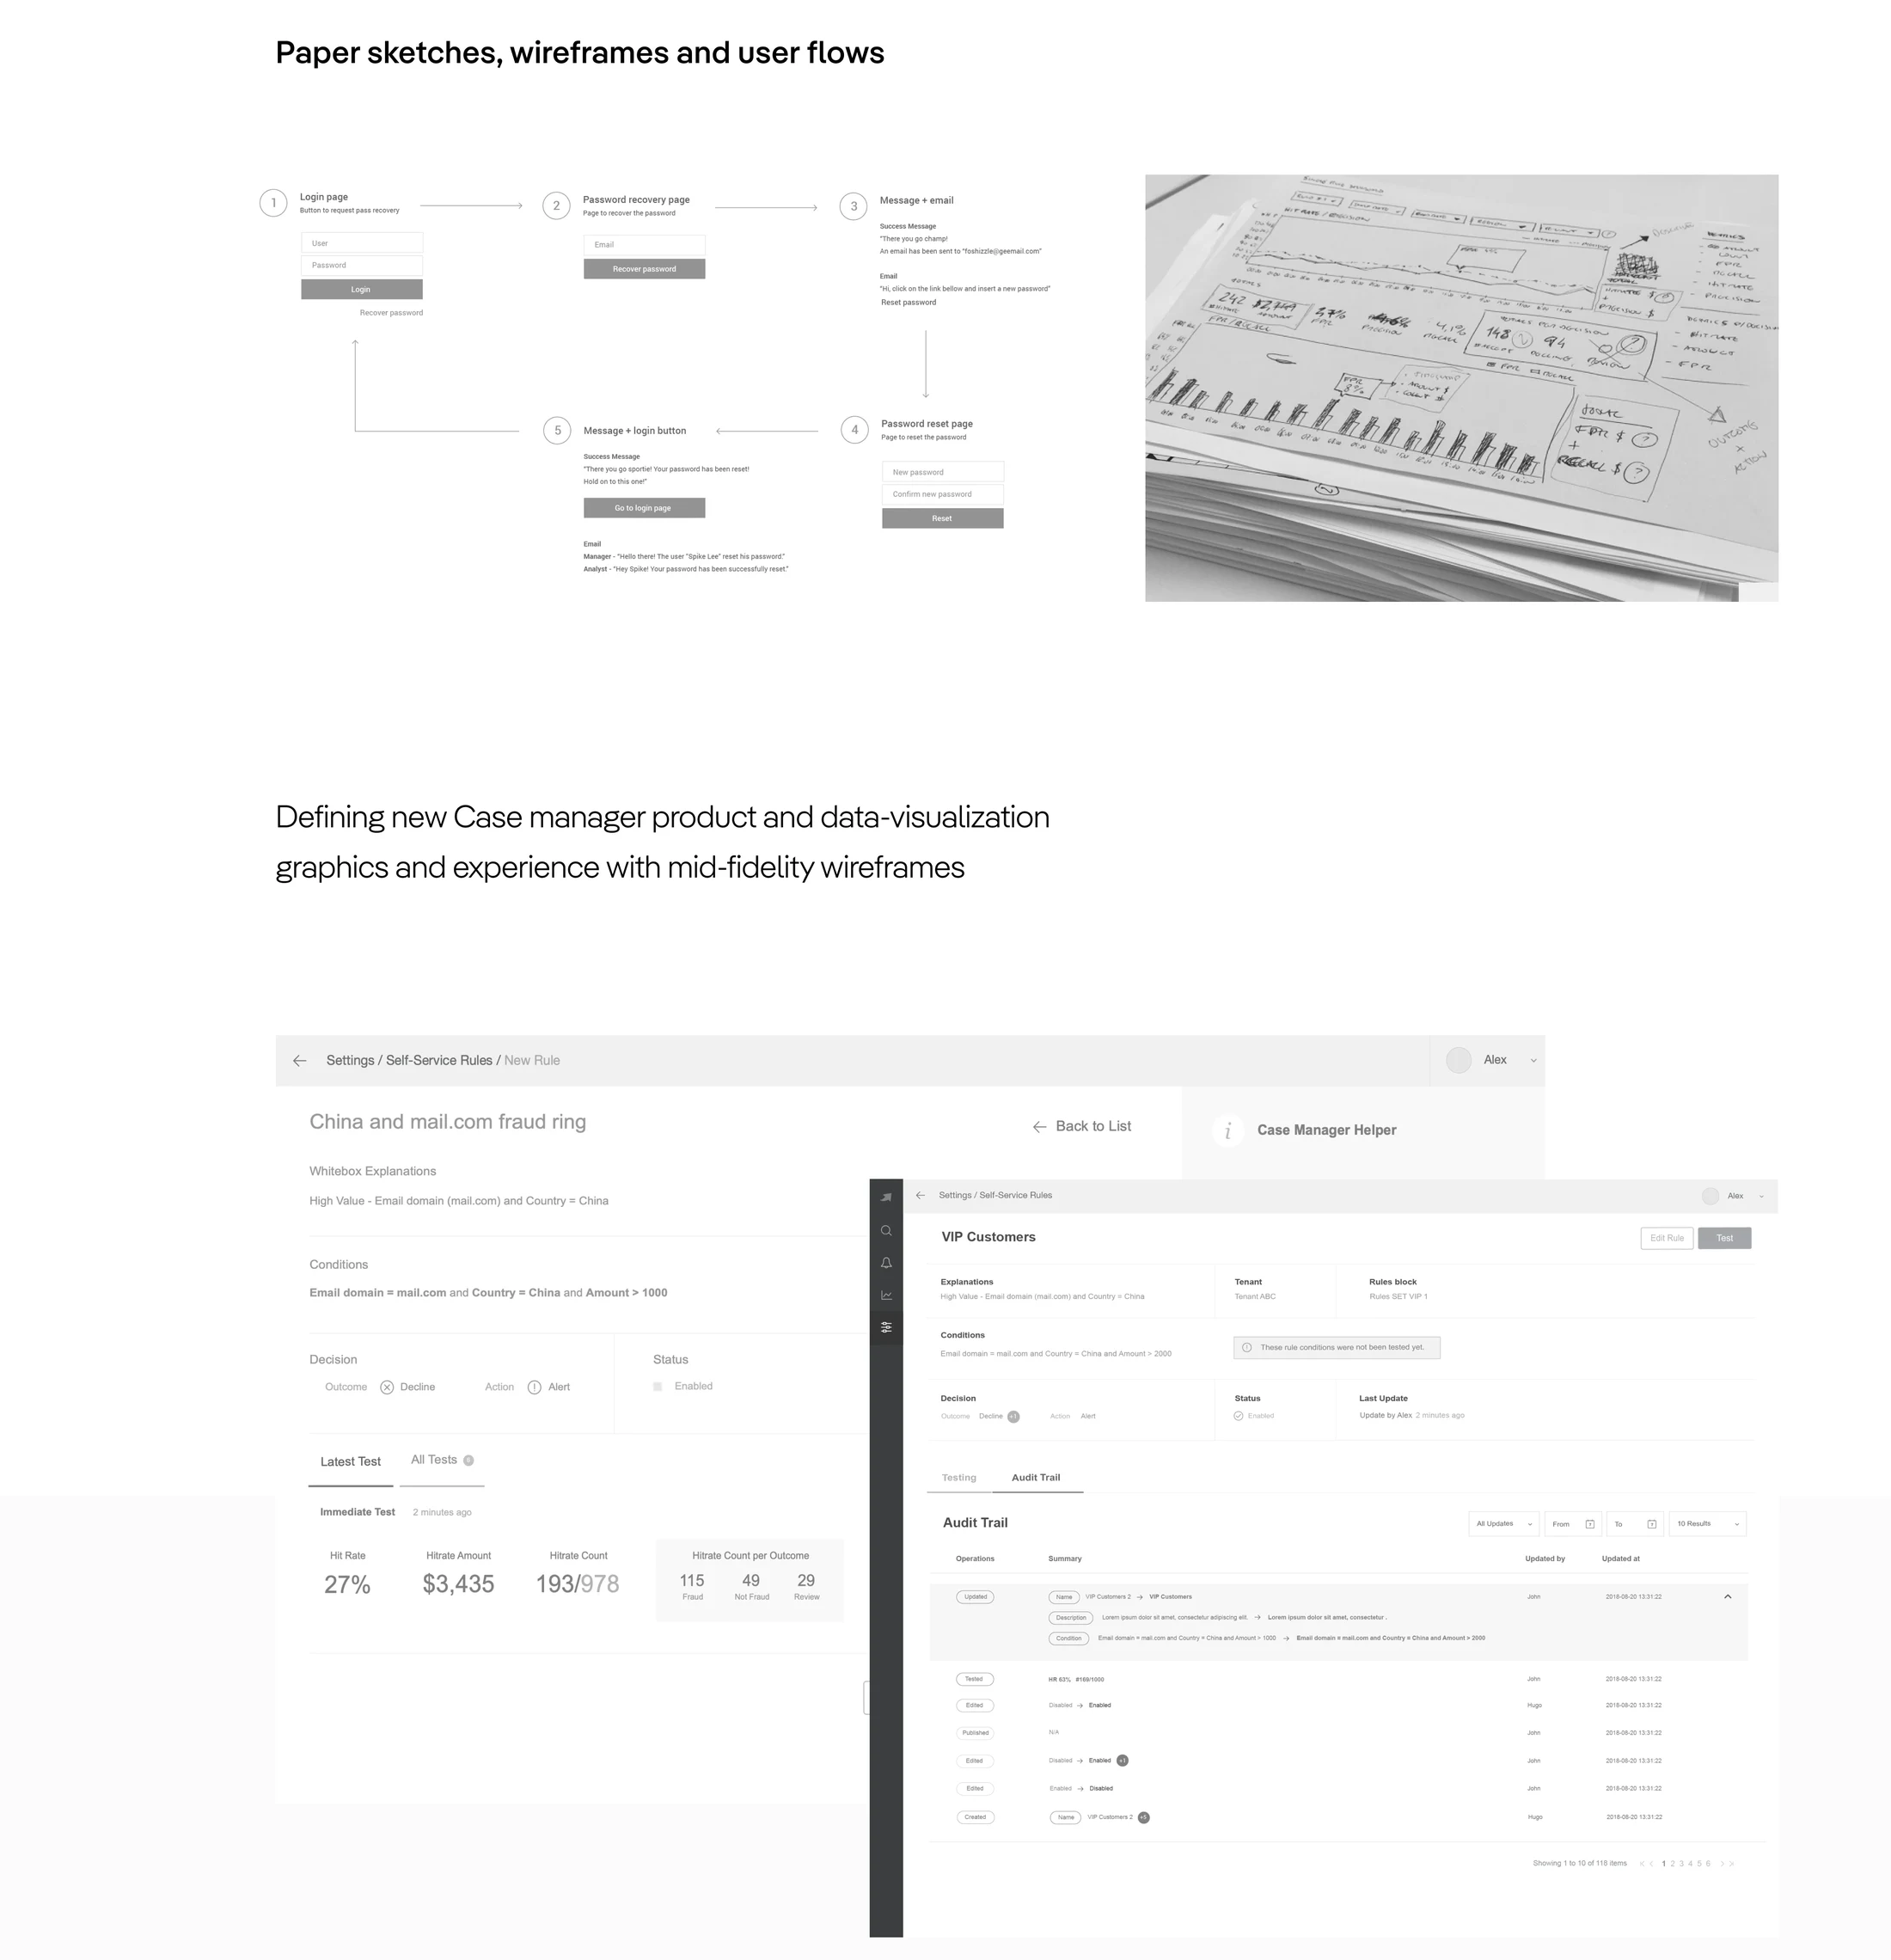
High-fidelity screens replaced the Alert Manager one workflow at a time, each tested through moderated sessions. The interface followed the analyst's decision process, not the data model, and Insights put ML output in a form compliance could trust.
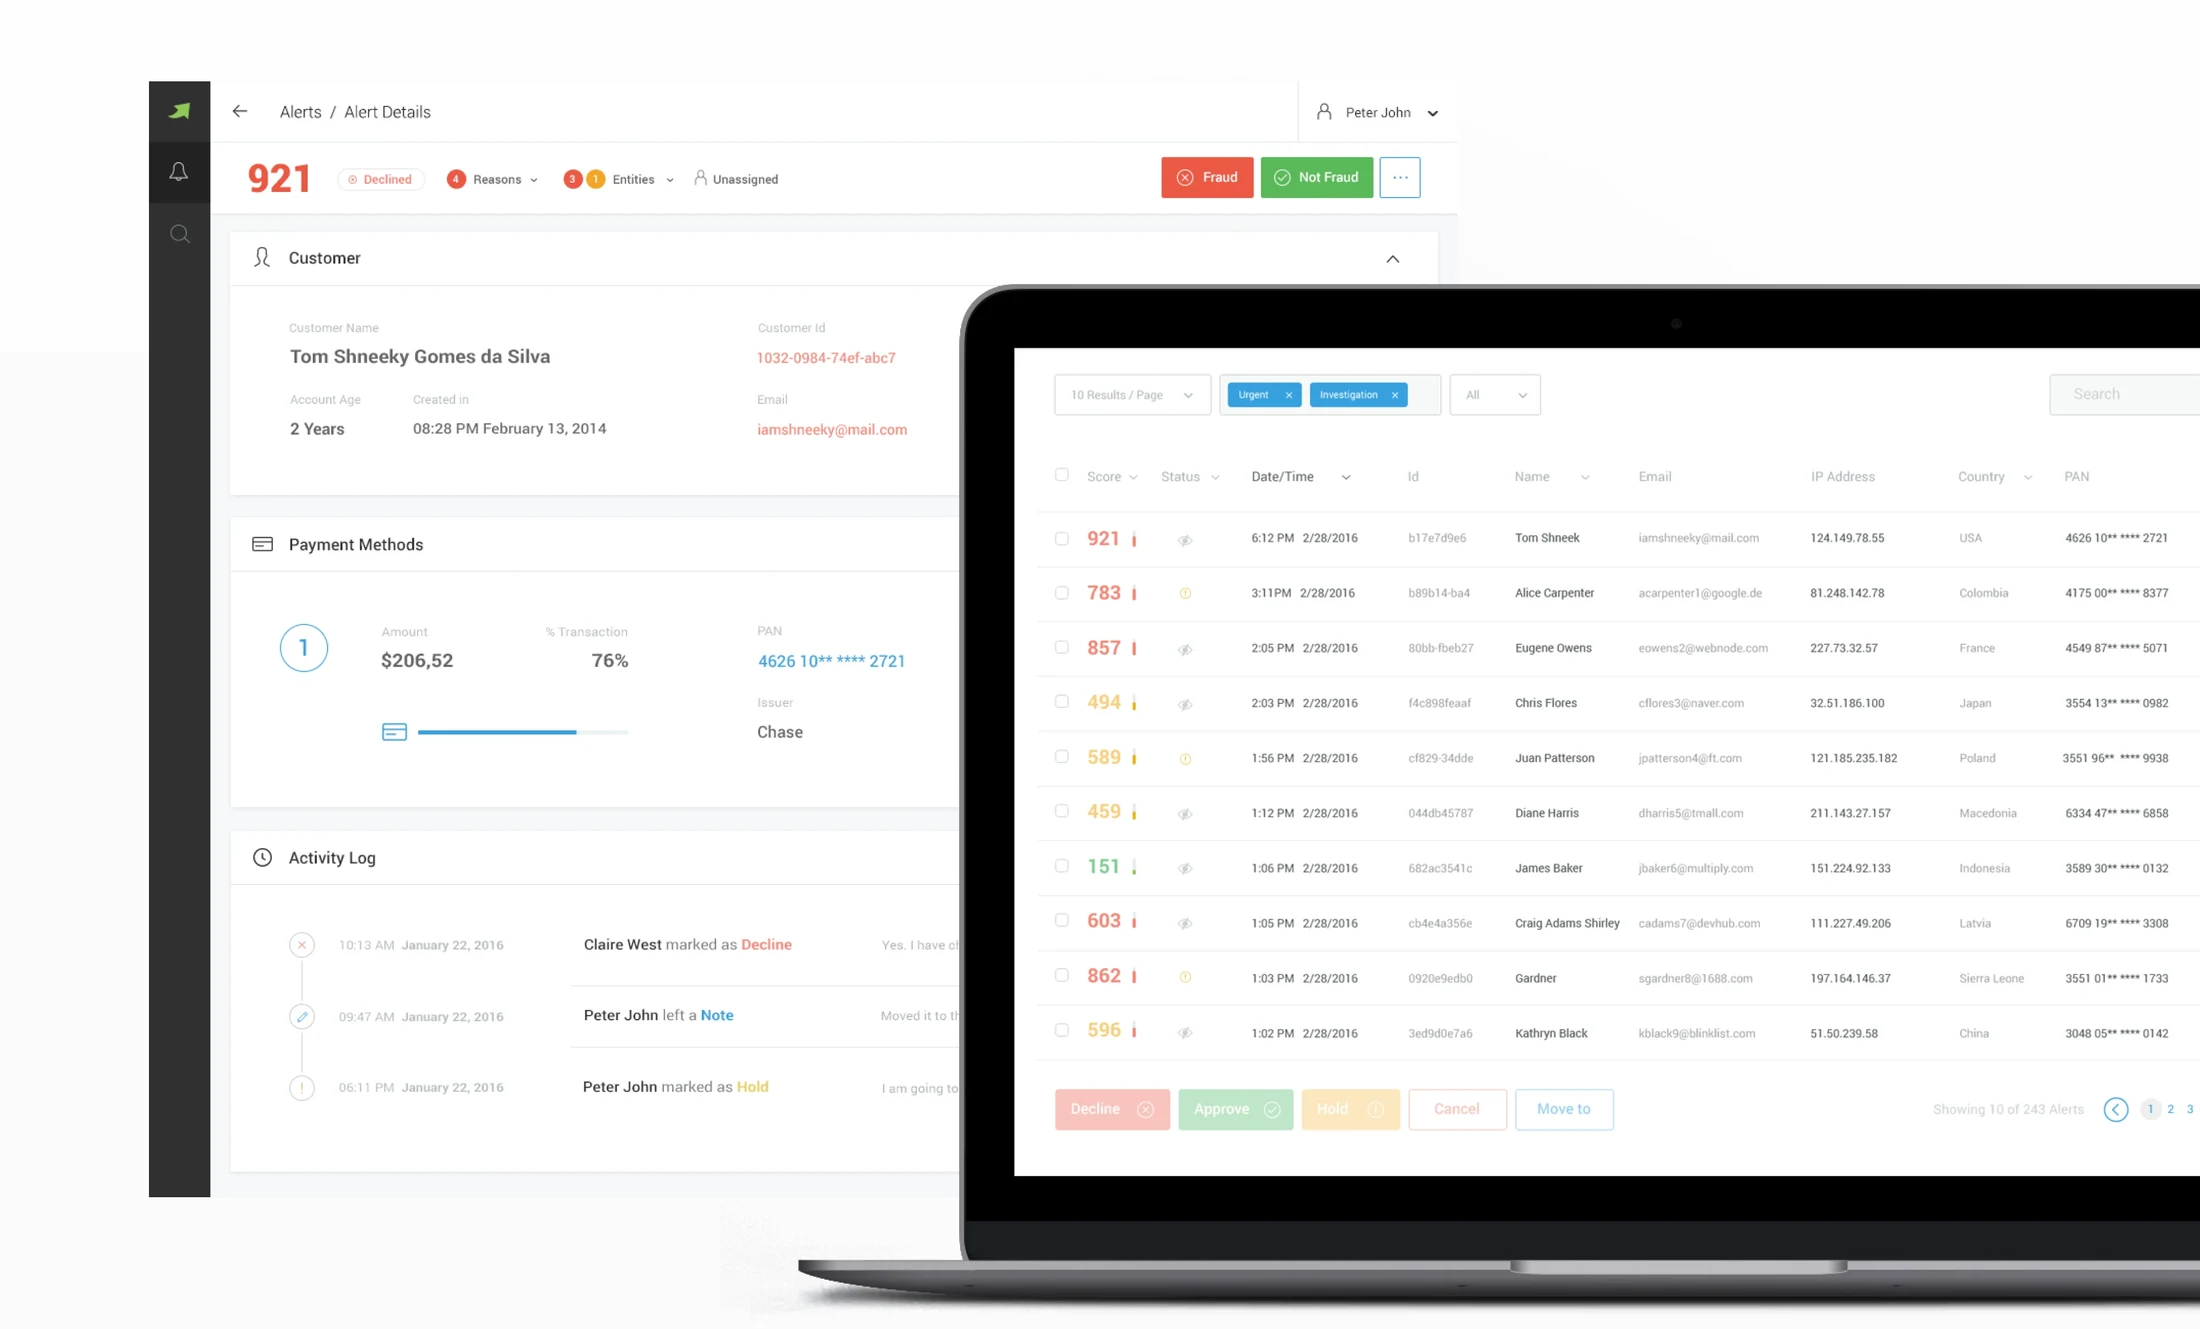
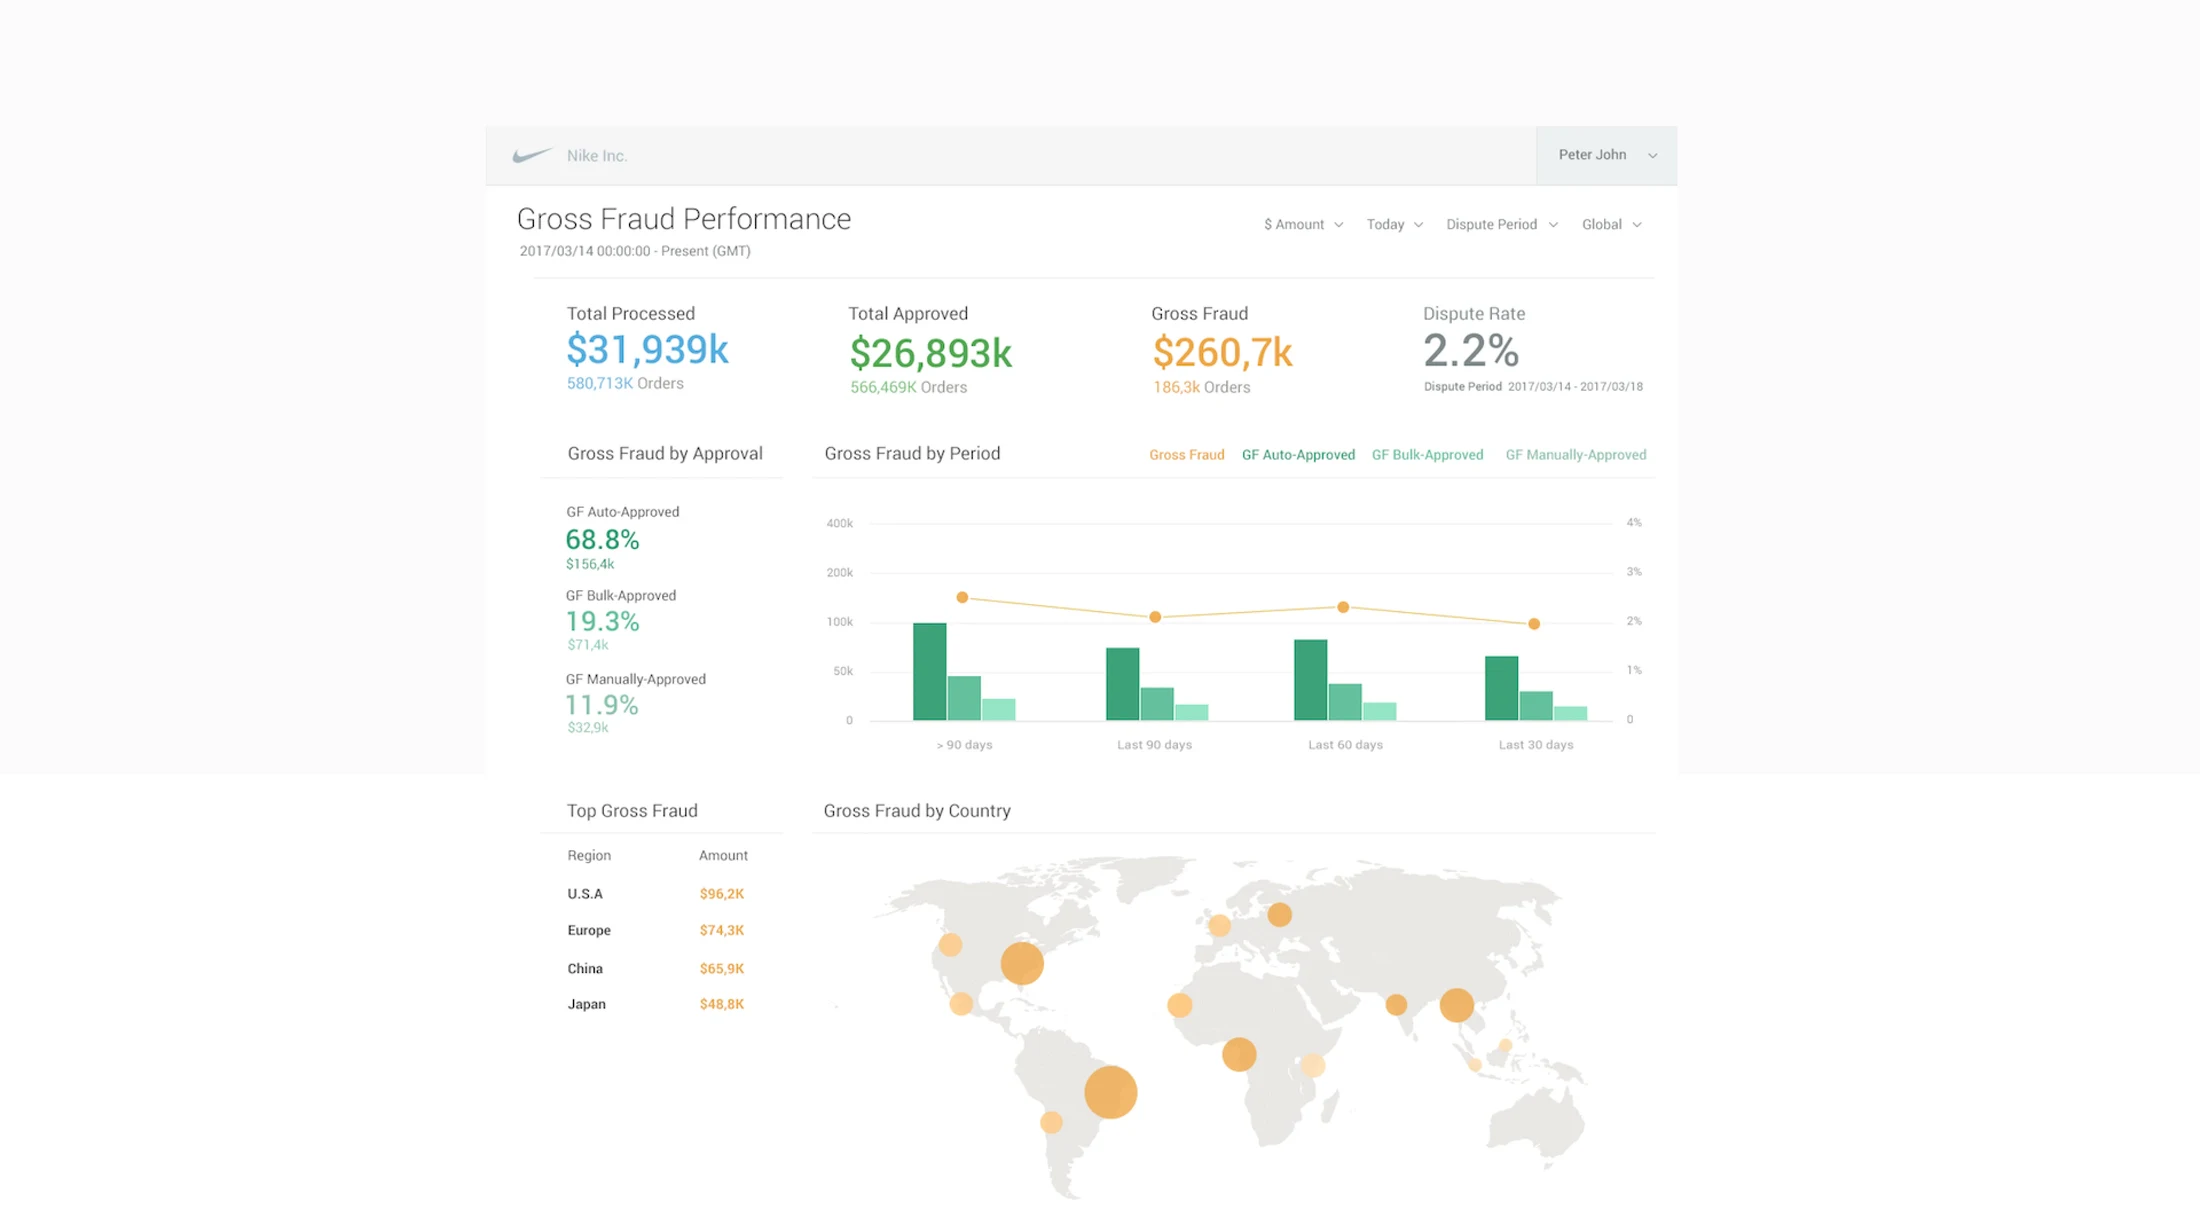
Case Manager: evaluative research
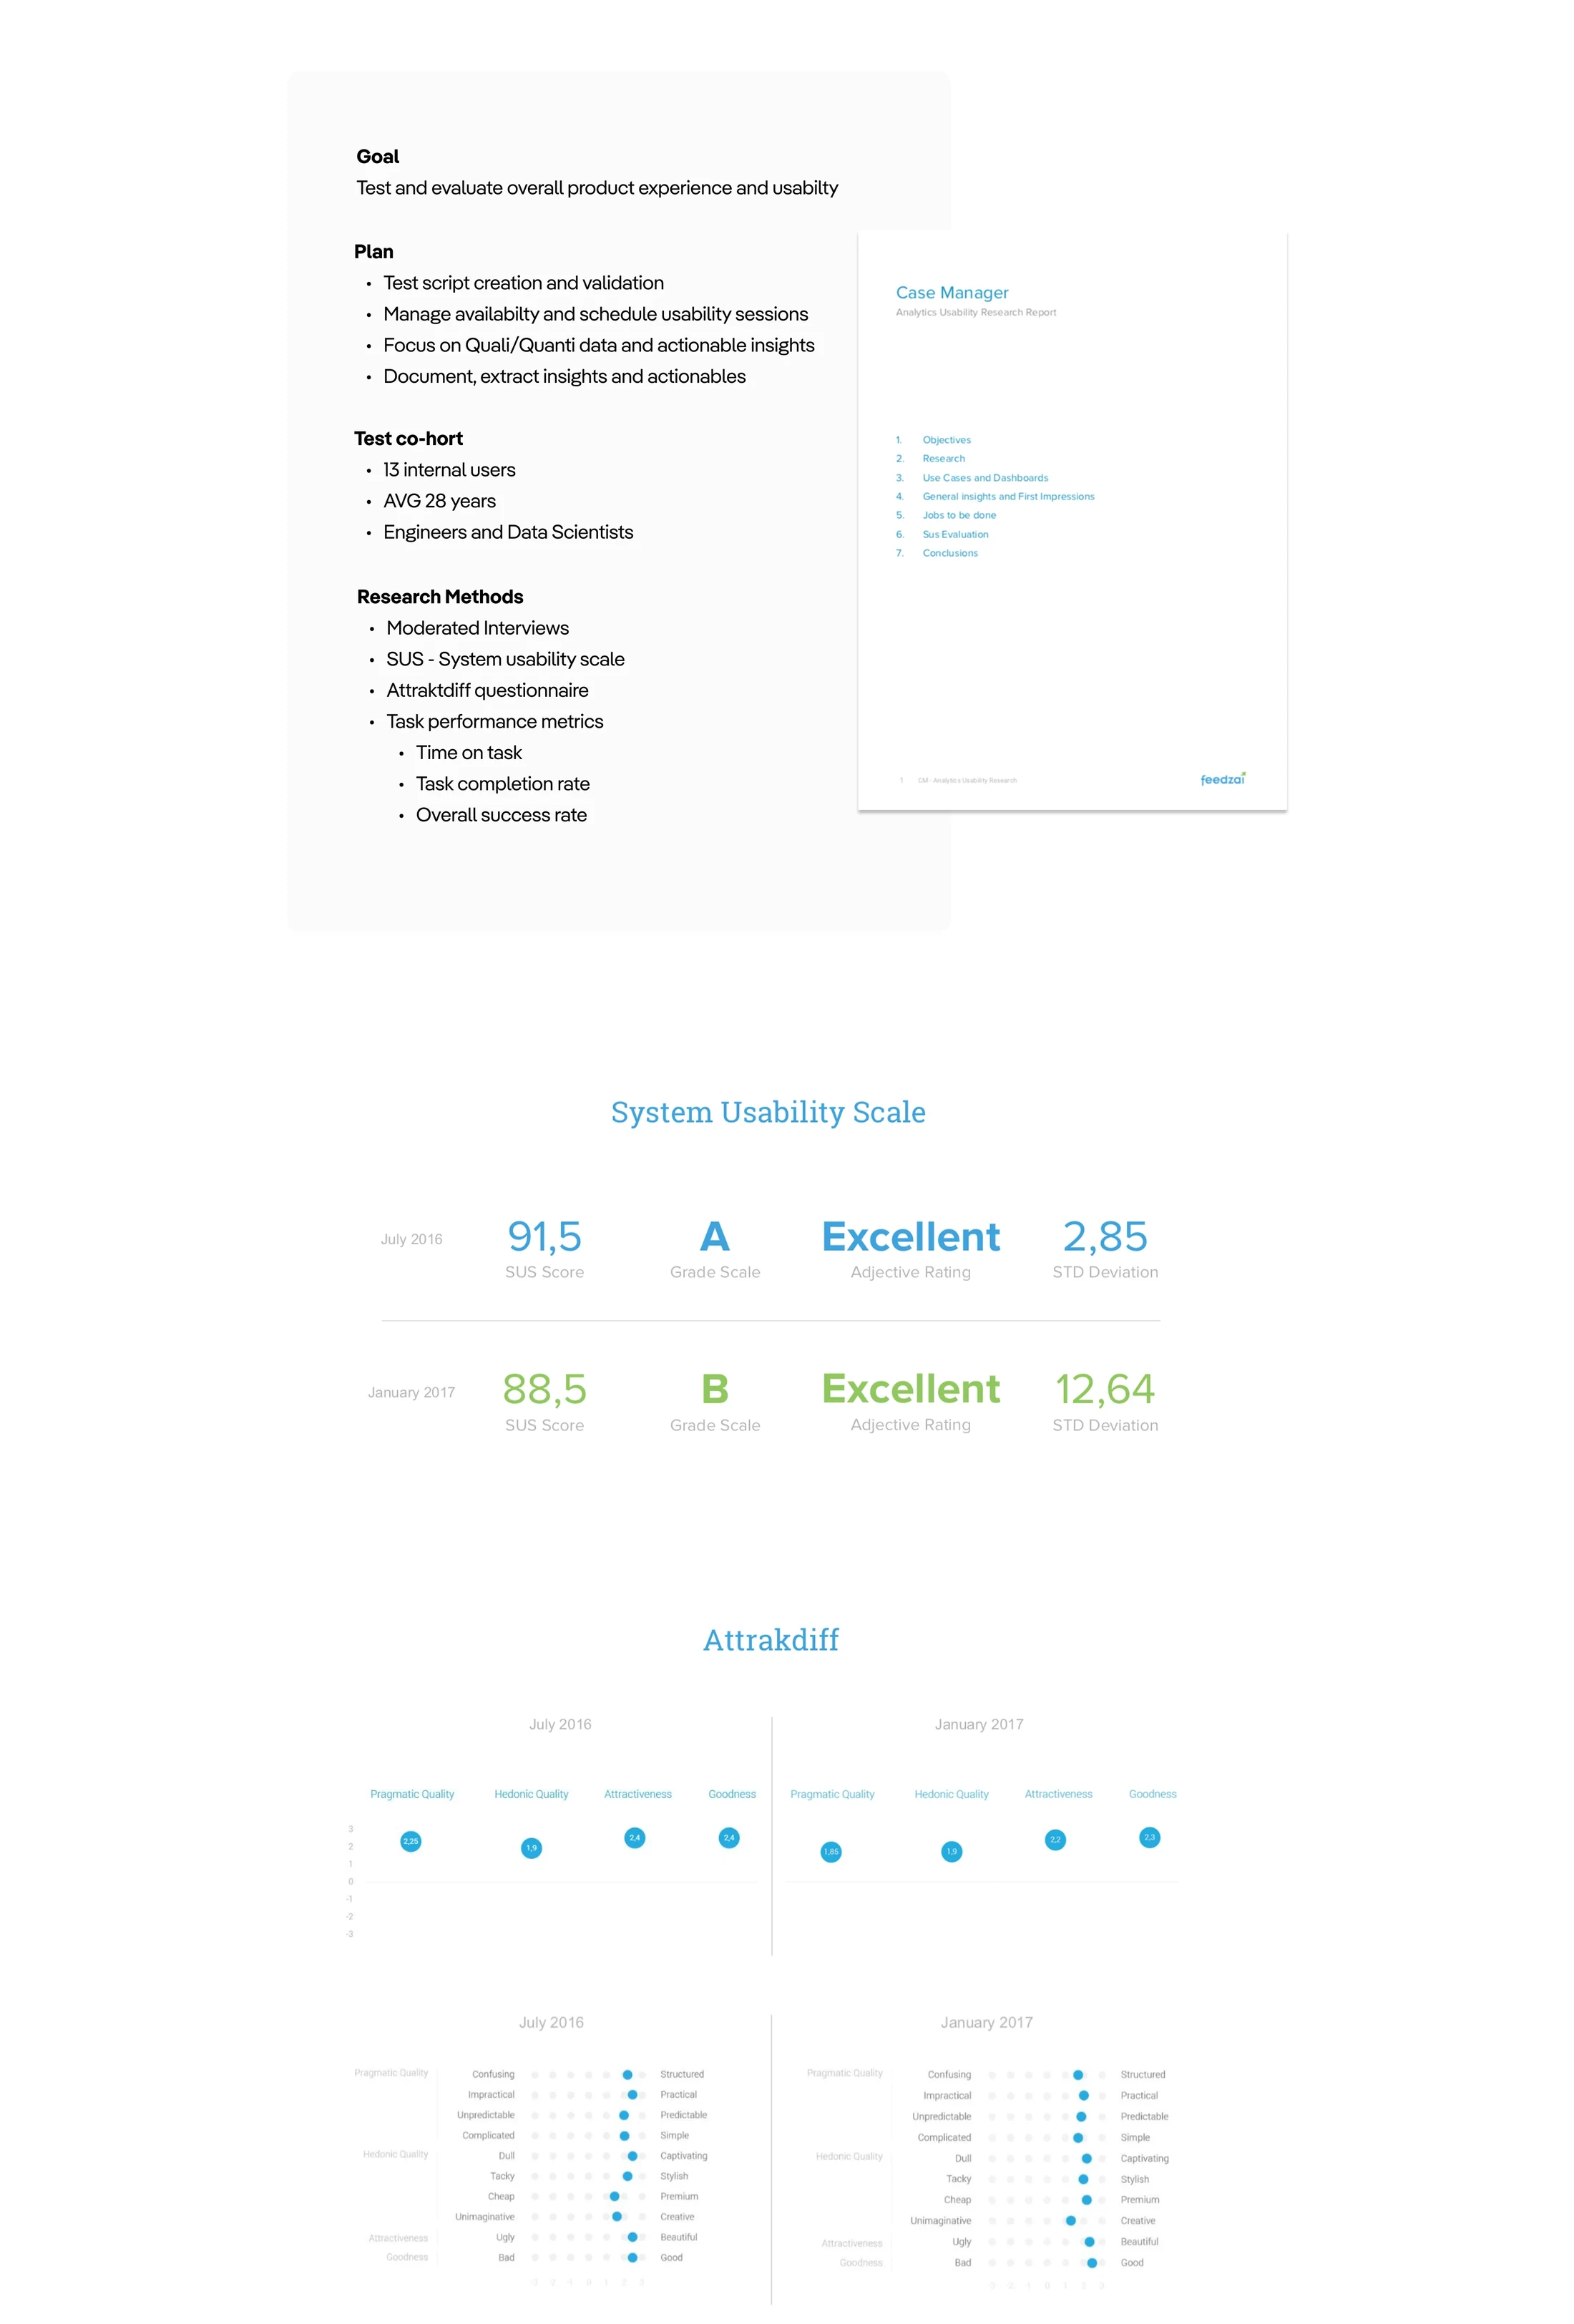
Recurring tests with a fixed cohort: task success, SUS, attrakdiff.
Usability testing sessions (July 2016 + January 2017)
Two calls that shaped the outcome
Design the AI as a collaborator, not an authority
The score was visible, never the headline. Analysts saw the evidence first, and caught errors automation would have missed.
Audit trail as a design constraint, not an afterthought
Every decision had regulatory weight. Building the audit trail in from day one, not as a later report, shaped every interaction.
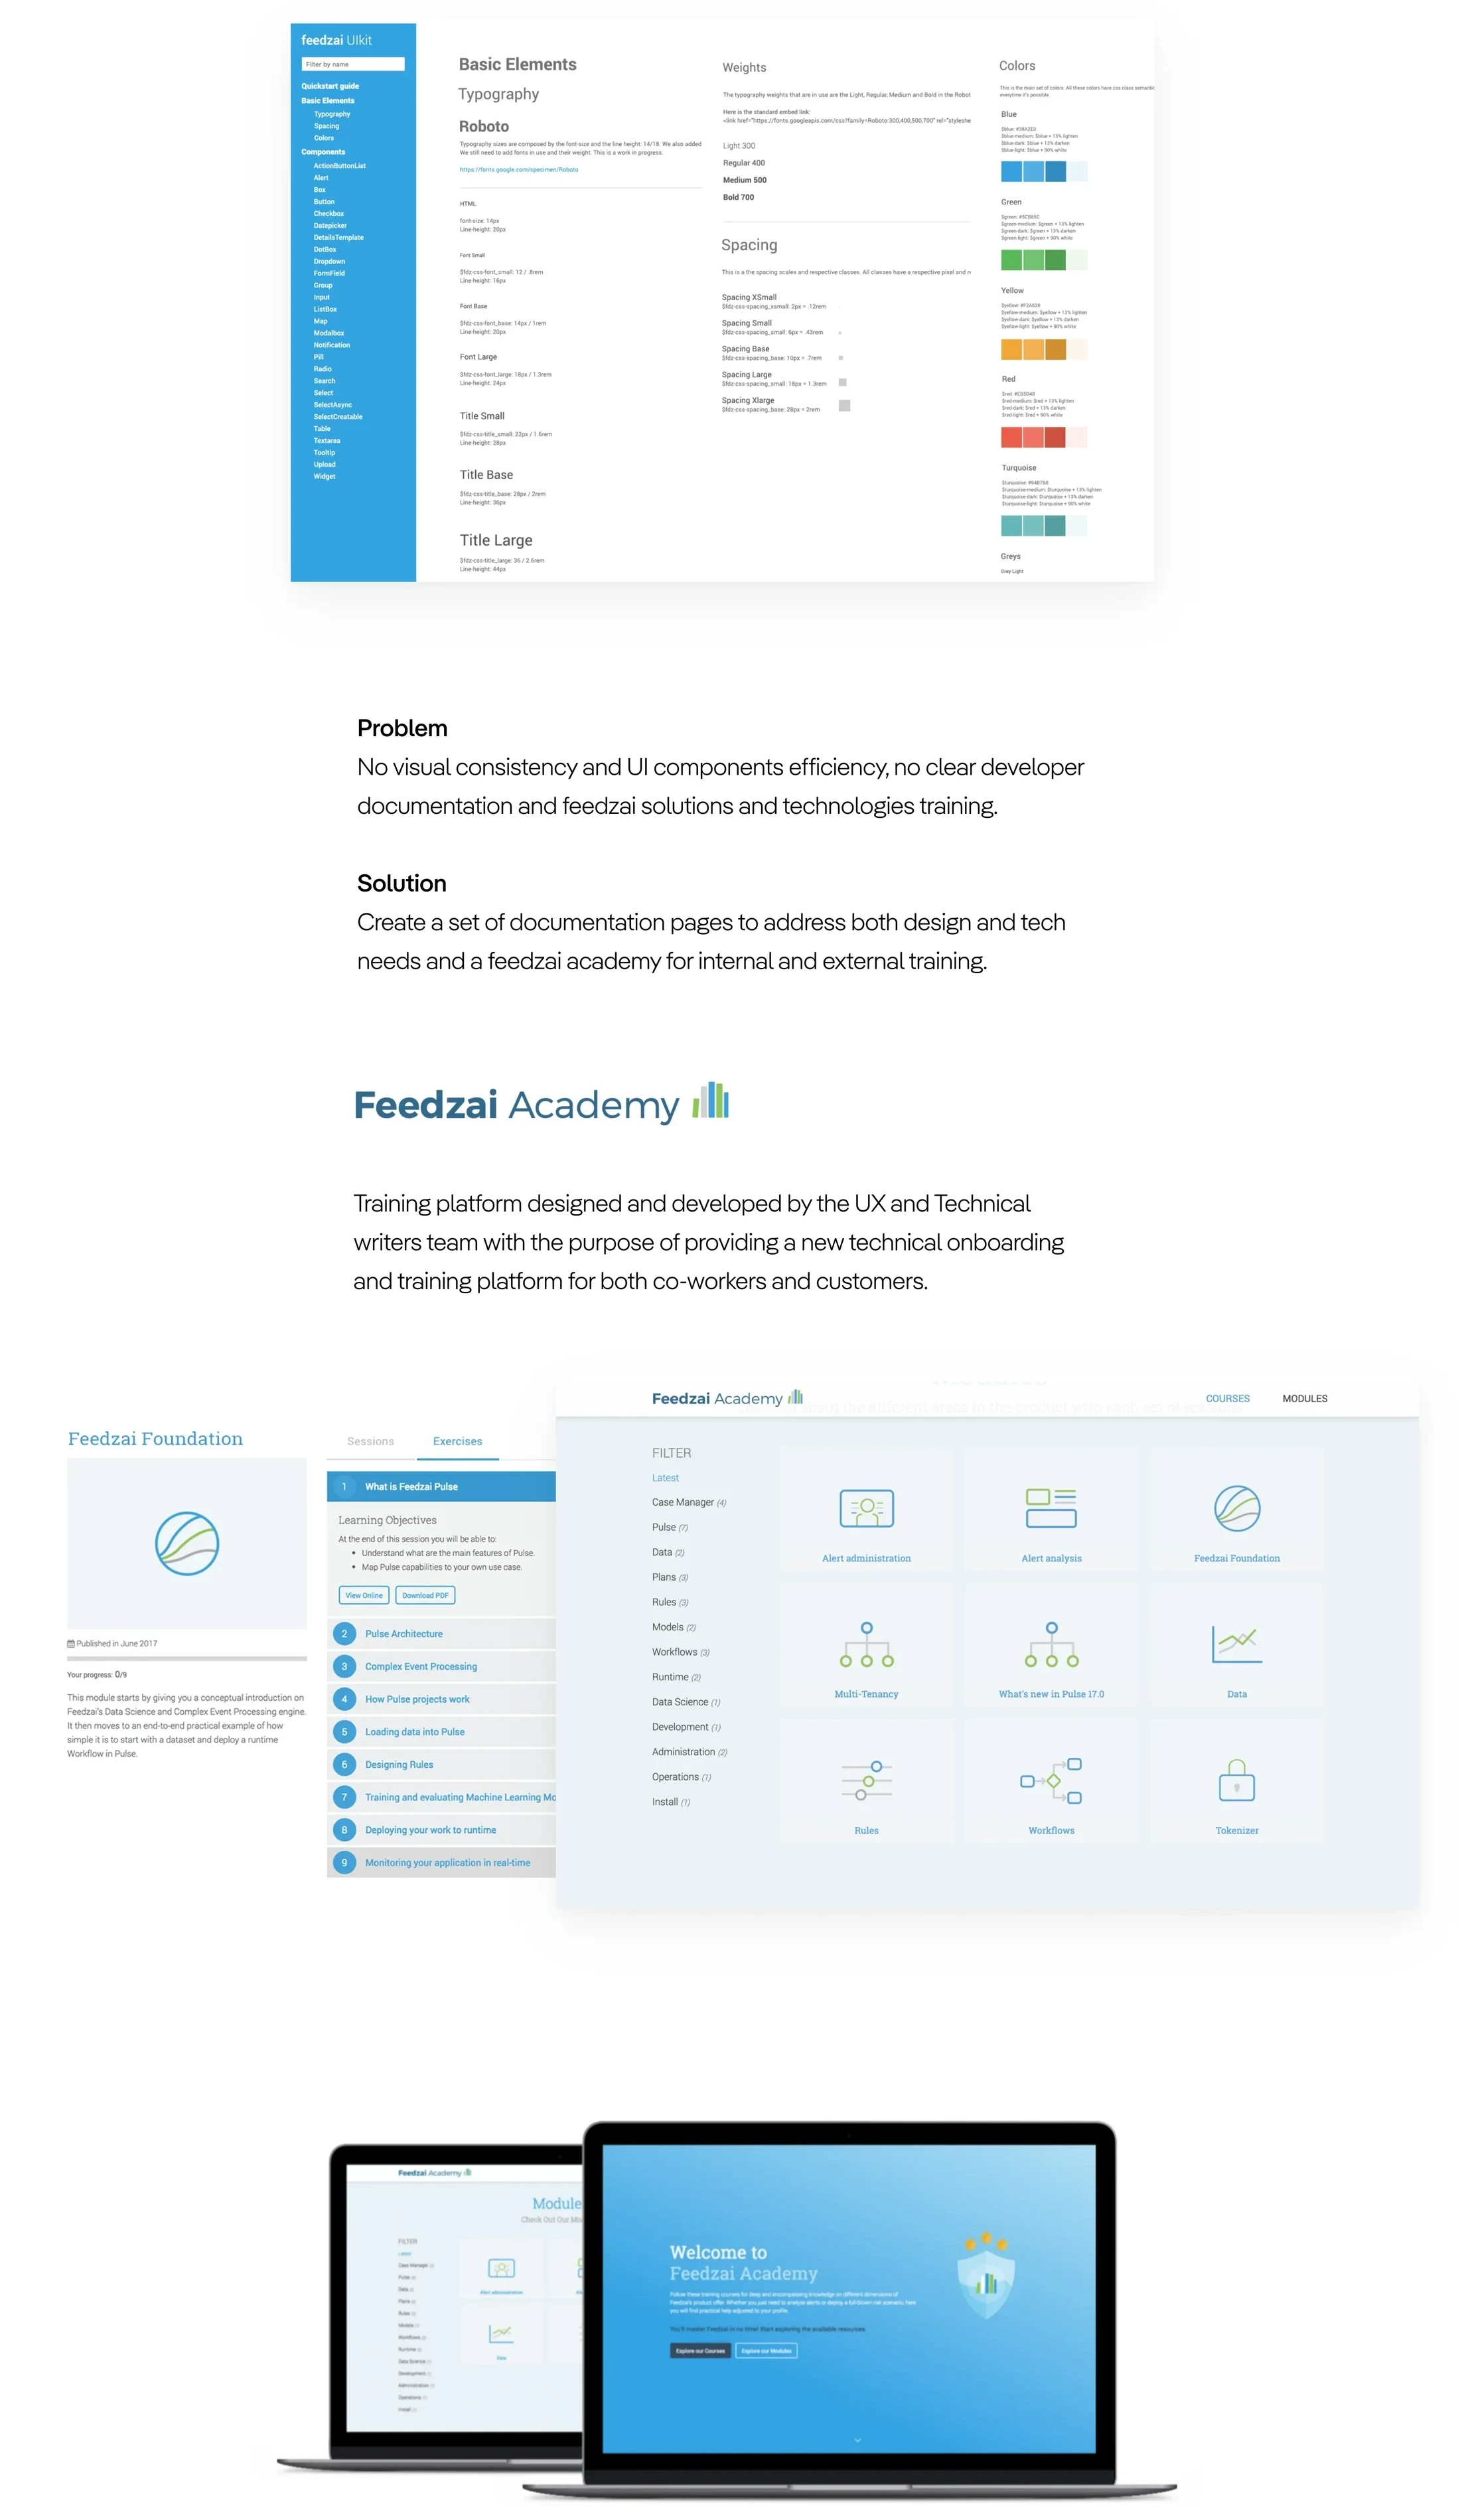
Components, documentation and academy
Scaling meant documenting it: a UI kit and a Feedzai Academy platform built with technical writing.
Products that analysts trusted
Where a bad decision carries financial consequence, trust is the only measure. Both became defining products in Feedzai's expansion.
What this changed
Feedzai is where I first designed alongside machine learning rather than in front of it. Making model output legible without eroding human judgment is a problem I have carried since.
The model score was never the headline. Evidence first, then the model's assessment.